Delivering NVIDIA RAG Blueprints as a Self-Service GPU Service
Retrieval-Augmented Generation (RAG) has become one of the most common architectures for enterprise generative AI. Instead of relying only on knowledge embedded in a large language model, RAG enables organizations to ground responses using their own documents, data, and knowledge repositories.
But deploying a production RAG environment involves much more than launching an LLM. A complete RAG stack can require embedding models, reranking models, document ingestion pipelines, search infrastructure, vision-language models, GPU scheduling, networking, ingress, model caches, and application endpoints.
For organizations operating GPU infrastructure, the challenge is straightforward:
How do you make this complete RAG stack available as a simple, repeatable service without requiring every user to become an expert in Kubernetes, NVIDIA NIM, Helm, networking, and GPU infrastructure?
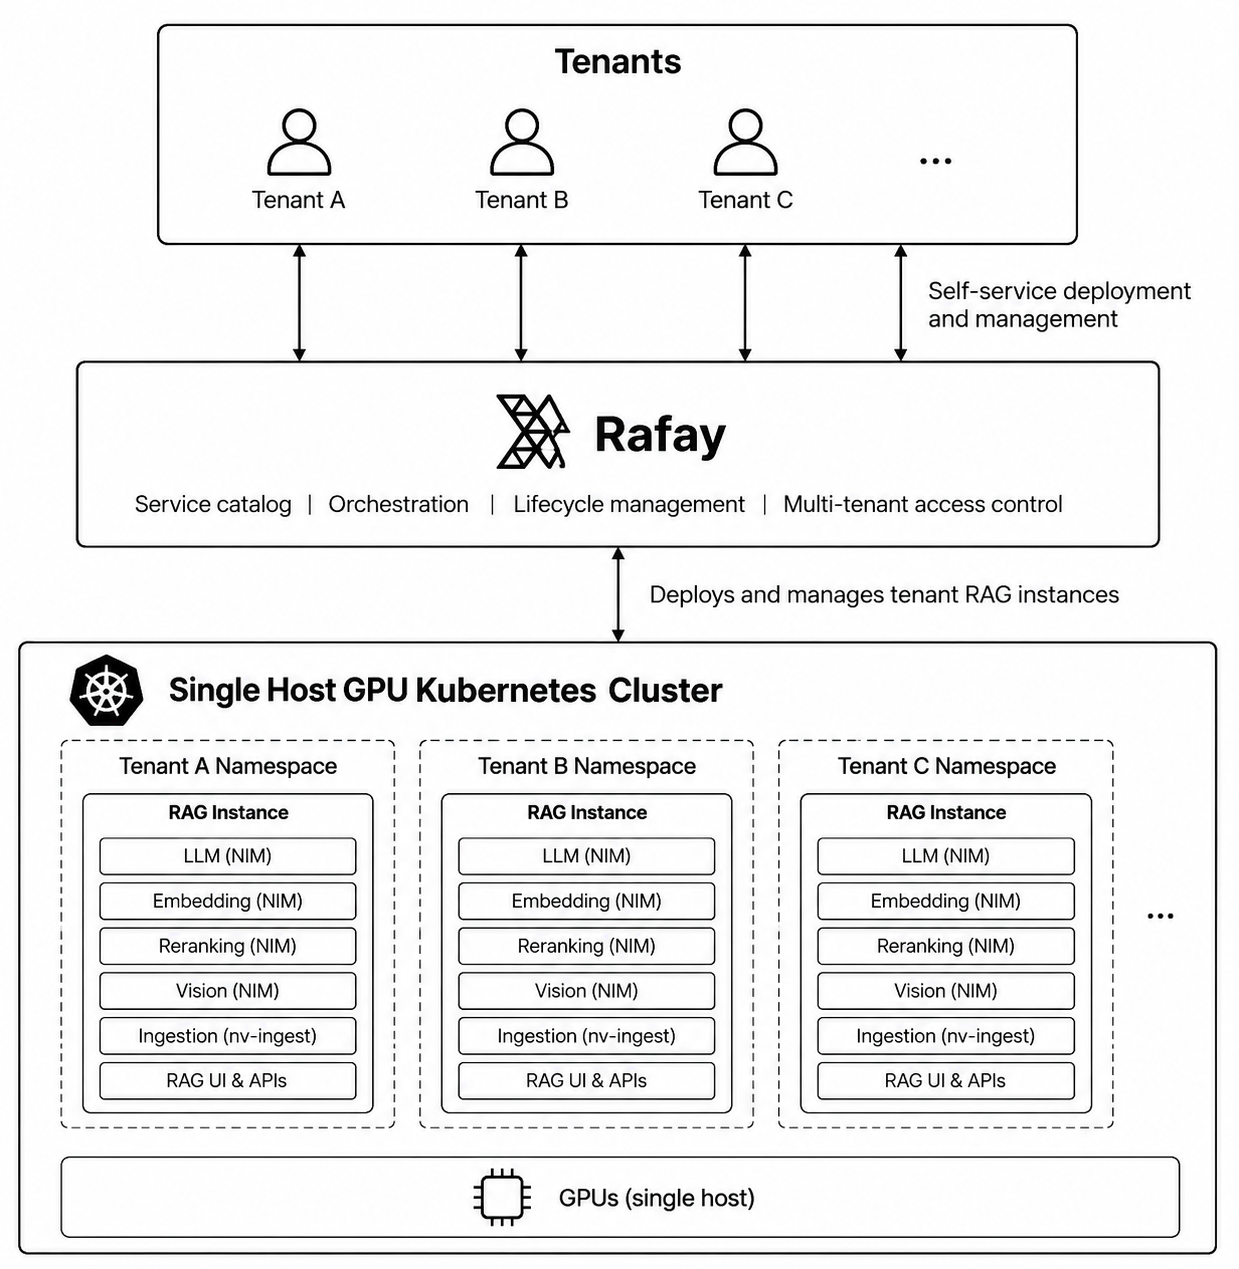
One approach is to package NVIDIA's RAG Blueprint as a self-service offering on top of a neocloud's GPU infrastructure. The result looks much more like a cloud service than a traditional Kubernetes deployment.